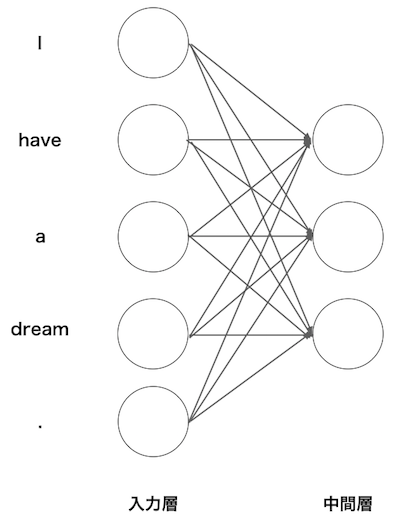
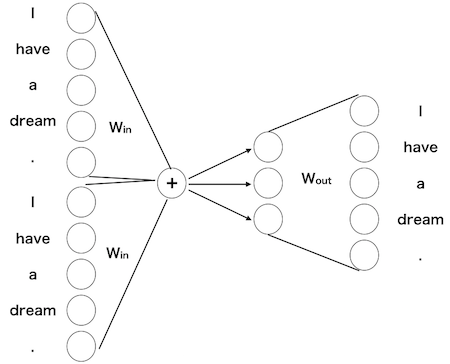
| 単語 | 単語ID | one-hotベクトル | |
|---|---|---|---|
| have | 1 | (0,1,0,0,0) | |
| dream | 4 | (0,0,0,1,0) |

import numpy as np
c = np.array([[1,0,0,0,0]])
W = np.random.randn(5,3)
W
array([[-0.99274046, 0.91070783, -0.92282515],
[-0.27036302, -0.60801496, -0.0442795 ],
[-0.11581048, 1.31737052, 1.50720364],
[-1.69308043, 0.10627303, -1.35713761],
[-0.37100892, 0.43867137, 2.95245187]])
np.dot(c,W)
array([[-0.99274046, 0.91070783, -0.92282515]])

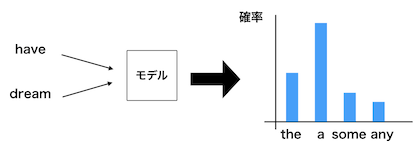
注: 元々はword2vecはパッケージの名称でしたが、この仕組み全体をword2vecと呼ぶようになりました。コンテクストからある単語を予測するモデルをContinuous Bag of Words (CBOW)と言います。
from nltk import sent_tokenize, word_tokenize
text_law = open("../corpus/eng_wikipedia_2016_100K-sentences.txt","r").read()
text_sent = sent_tokenize(text_law)
text_word = []
for t in text_sent:
text_word.append(word_tokenize(t.lower()))
../corpus/eng_news_2023_100K-sentences.txtもありますので時間があれば試してみてください。# 中身の確認
print(text_word[0:2])
[['0.41', '%', 'of', 'the', 'population', 'were', 'hispanic', 'or', 'latino', 'of', 'any', 'race', '.'], ["'06", 'dtas', 'appear', 'to', 'have', 'made', 'essentially', 'simultaneous', 'and', 'duplicative', 'amendments', 'to', 'the', 'code', 'and', 'its', 'notes', '.']]
# word2vecのimport
from gensim.models import Word2Vec
# インスタンスの生成
model = Word2Vec(text_word,vector_size=100,window=5,min_count=5,workers=4)
# text_word: 対象の単語列
# size: 中間層の数(分散表現の次元)
# window: 周辺単語の数
# min_count: カウントする単語の最小出現数
# workers: 処理のスレッド数(とりあえず、4を引数とする)
# モデルの学習
model.train(text_word,total_examples=len(text_word),epochs=100)
# text_word: 対象の単語列
# total_examples: 対象の単語列の要素数
# epochs: 学習回数
(162621294, 238416200)
# 得られた分散表現の確認
model.wv["computer"]
array([ 1.60997462e+00, 1.11882865e-01, -4.60914087e+00, -5.10409594e-01,
-7.12604746e-02, -4.47935909e-01, -1.65029490e+00, -3.44638729e+00,
5.65168083e-01, -1.53856361e+00, -2.42521906e+00, 1.63483524e+00,
-7.96969891e-01, -2.12511778e+00, 7.80295193e-01, -2.61581898e+00,
-1.03619683e+00, -1.94017816e+00, 1.16454649e+00, -1.57105243e+00,
9.77434933e-01, 1.36574376e+00, 1.29647422e+00, -9.28313509e-02,
7.93517172e-01, -3.01373094e-01, -2.55642414e+00, -8.13521743e-01,
1.51849735e+00, -1.40114510e+00, -1.10132420e+00, 2.10249424e+00,
2.09025955e+00, -1.95234275e+00, -3.00608778e+00, -3.15004021e-01,
-1.56109226e+00, 6.42928839e-01, 1.02741134e+00, 2.38829747e-01,
2.09406853e+00, 2.81850028e+00, -3.97406995e-01, -1.59815118e-01,
-8.08480024e-01, -1.44024193e+00, -3.51690084e-01, 2.22859621e+00,
1.13347971e+00, 4.68875468e-01, 8.85890186e-01, 1.55484009e+00,
4.91799772e-01, 4.23308939e-01, -4.50764269e-01, 1.33717582e-01,
1.63281059e+00, 6.08509958e-01, -4.85430891e-03, -7.09921539e-01,
1.25396860e+00, 1.07608938e+00, 1.83186901e+00, 1.37868750e+00,
-5.14116907e+00, 1.25095809e+00, 4.28599072e+00, -1.04849353e-01,
-1.75077629e+00, 1.42522633e+00, 3.51182318e+00, 2.57383406e-01,
7.99139321e-01, -9.35431957e-01, 1.43071026e-01, -3.92619848e+00,
7.14176238e-01, -3.28455210e+00, -1.66045475e+00, -1.54665565e+00,
3.50512892e-01, 9.41347599e-01, -6.56661749e-01, -3.72268796e+00,
5.31854033e-01, -1.09487045e+00, -1.06550908e+00, 1.07085931e+00,
-1.11551988e+00, -6.85167074e-01, 1.66576874e+00, 1.20583940e+00,
2.87590218e+00, -1.31999075e+00, 3.89516741e-01, 2.62307358e+00,
1.67861164e+00, 1.84681201e+00, -6.46027982e-01, 1.64312267e+00],
dtype=float32)
# 似た意味の単語Top 10
# 0から1の値をとり、0が似ていない、1が同じ意味。
model.wv.most_similar("cat")
[('mother', 0.4784231185913086),
('steed', 0.46737778186798096),
('protagonist', 0.4542187750339508),
('wasp', 0.45006805658340454),
('2576george', 0.4479040801525116),
('cloak', 0.44517040252685547),
('bundles', 0.4424614906311035),
('vision', 0.4396803677082062),
('shoes', 0.43948787450790405),
('judas', 0.43883079290390015)]
# 2つの単語の類似度
model.wv.similarity(w1="dog",w2="cat")
np.float32(0.3824771)
# 2つの単語の類似度
model.wv.similarity(w1="dog",w2="pig")
np.float32(0.5467384)
# 仲間外れを見つける
model.wv.doesnt_match(["windows","apple","banana"])
'banana'
# 与えられたコンテクストで出現する確率が高い単語
model.predict_output_word(["apple","notebook"],topn=10)
[('ibm', np.float32(0.34531182)),
('ii', np.float32(0.17561474)),
('mac', np.float32(0.05369249)),
('pc', np.float32(0.02616909)),
('graphics', np.float32(0.01896321)),
('printers', np.float32(0.015708247)),
('macintosh', np.float32(0.013771329)),
('portable', np.float32(0.012304742)),
('apple', np.float32(0.011901883)),
('intel', np.float32(0.008603544))]
# TokyoからJapanを引くと
model.wv.similar_by_vector(model.wv["japan"] - model.wv["tokyo"])
[('japan', 0.6974197626113892),
('china', 0.48486343026161194),
('europe', 0.48235371708869934),
('india', 0.43301618099212646),
('germany', 0.4246027171611786),
('argentina', 0.41957131028175354),
('apartheid', 0.40759968757629395),
('america', 0.4054245948791504),
('dynasty', 0.40479332208633423),
('separatist', 0.4028787910938263)]